The Night the Mac Died
On 14 June, my 24 GB MacBook Air stopped being a useful engineering machine. Several agent-assisted jobs were running at once, the interface hung, and I had to force a reboot. The incident report recorded recovery without data loss, but the active sessions and their work were disrupted. The immediate problem was memory exhaustion. The more useful question was why a collection of individually reasonable requests had been allowed to create an unreasonable workload together.
I was directing the work and reviewing the changes, with coding agents helping implement them. After the crash, I wanted sessions to stop launching more agents than the Mac could handle. When the guard refused a request, I wanted that refusal to warn me that we were approaching the same problem again, so I could reduce the workload or move it to the desktop. This episode follows the guard we added, how it made that decision, and the limits it still had.
Every session had a plan. The machine had one memory budget.
The 88-video job was a research-discovery task: VW-812, a broad “provocation digest” for finding ideas worth exploring. I wanted an inexpensive first pass across a large set of YouTube material, producing leads I could review and decide whether to investigate more deeply. The intended value was breadth: encountering an unfamiliar approach or a different way of framing a problem could suggest something worth trying in Rootweaver.
“Provocation” meant an idea that prompted a useful question. The skim was intended to help me choose what deserved attention; deeper analysis against the actual system would be a separate step. An interesting suggestion was still a lead to investigate, not an established finding or an implemented improvement.
That research skim was the workload that tipped the balance. I had already intended the 88-video job to run in a solo session. Instead, four general-purpose subagents were skimming batches of 22 videos while other work continued. The incident report describes those agents holding video transcripts and fetched material in their contexts. A code-cartographer was mapping a package import seam, a memory-consolidation job was running, and three Claude Code sessions were open. The incident was recorded under VW-813, the MacBook memory-exhaustion investigation.
The problem was the combined load. Four agents were working on the digest while other sessions and background jobs were also using the laptop. Splitting a task into batches could finish it faster, but launching those batches together could exhaust the same 24 GB of memory.
A small-batch rule already existed, but instructions in one session could not see what other sessions had launched. I needed the next dispatch to check the machine first, stop when the configured limit was reached, and explain why it had stopped.
The report listed eight Python processes with memory figures ranging from roughly 2.8 to 4.6 GB each. It also recorded a substantial compressor footprint and very little free memory when the system began jettisoning processes. Those findings supported the conclusion that aggregate demand had overwhelmed the machine. They did not provide a clean accounting equation in which every reported process figure could simply be added to the physical RAM total.
| Recorded indicator | Historical report | What I take from it |
|---|---|---|
| Installed unified memory | 24 GB | One shared physical budget |
| Listed Python processes | 8 | The load was spread across multiple processes |
| Individual reported process figures | 2,846–4,608 MB | Workers were substantial, not negligible helpers |
| Free memory at the recorded kill point | 175.6 MB | Little immediate headroom remained |
| Compressor footprint | 13.5 GB | Compression was already carrying a large burden |
The eight listed process values sum to 29,433 MB. That is a sum of reported accounting figures, not a measurement of 29,433 MB of unique physical memory. Shared pages, compression and the definitions used by the report matter. I have not freshly re-read the original crash files for this reconstruction, so I am keeping the distinction explicit rather than turning a striking number into false precision.
The surrounding applications mattered as well. The report identified browser renderers, VS Code, Obsidian, MCP servers and the CLI as contributing tenants. A worker cap cannot assume an otherwise empty laptop. The same number of agents can be tolerable after a clean restart and risky when an editor, browser and several sessions are already active.
Move the decision before the next worker starts
The first corrective change was VW-814, a session-aware RAM guard and a separate low-memory tripwire. Its useful move was to check the shared machine before another subagent started. The guard was registered on Claude’s Agent and Task tool calls, so it could refuse a dispatch while the work was still a request rather than an additional memory-consuming process.
There were two questions to answer. Would this request take the estimated worker count beyond the host’s cap? Was the estimated available memory already below its floor? Either reason could stop a dispatch on the MacBook. A count bound limited the size of a burst; a memory bound acknowledged that other applications could consume the remaining headroom.
The host policy lived in a configuration file rather than being repeated through each session’s instructions. Hostname detection selected the MacBook, desktop or default policy. That was a practical local convention, not a general discovery system. Its reliability still depended on the machine being classified correctly.
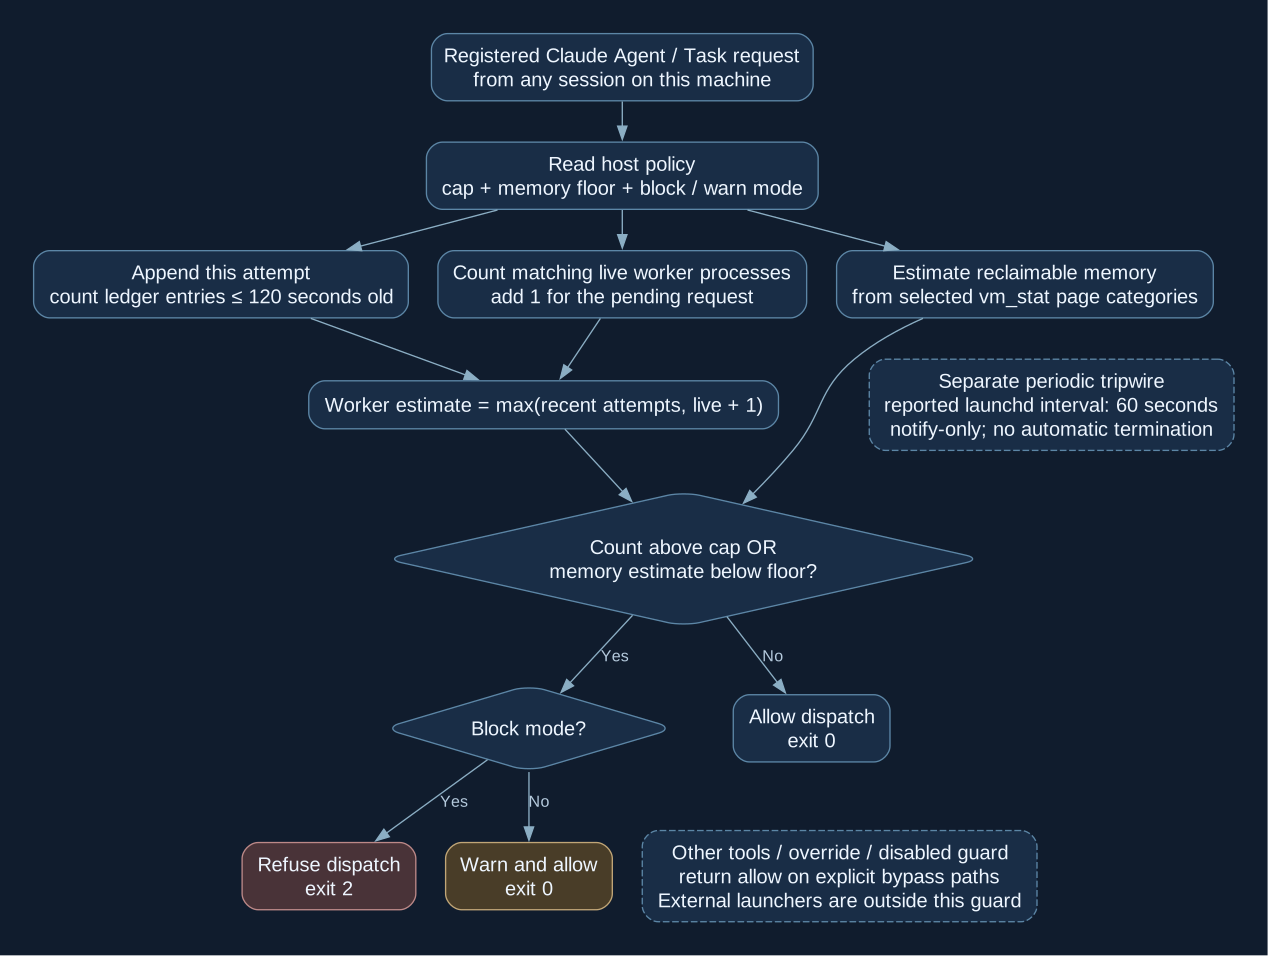
The implementation stayed small: a Python hook, one JSON policy file, a shared timestamp ledger and a process-name lookup. It did not introduce a scheduling service. That made it relatively easy to install, but it also meant the estimates and filesystem behavior needed to be understood on their own terms.
    now = time.time()
    avail_mb, _ = _available_mb()
    inflight = _inflight_count(ttl, now)
    live = _live_subagent_count()
    concurrency = max(inflight, live + 1)  # +1: the dispatch about to happen
Explain this code line by line
- Line 1: Read the current wall-clock time. The ledger uses it to age dispatch records.
- Line 2: Ask the memory helper for its available-memory estimate. The underscore discards the returned page size here.
- Line 3: Add this dispatch attempt to the shared ledger and count entries within the configured time window.
- Line 4: Count currently visible processes whose command line matches the worker pattern.
- Line 5: Take the larger estimate. The ledger already includes this attempt; the live process count needs one added because the requested worker has not started yet.
Taking the maximum is significant. Adding the two counts would often count the same work twice: once as a dispatch record and again as a running process. Taking the larger one gave two imperfect observations a chance to catch what the other missed. It was still a heuristic, not an exact inventory with a proven identity match between every ledger entry and process.
For example, after the cap was revised to three, two matched live workers plus the pending request produced an estimate of three. That could be allowed if the memory floor also passed. Three live workers plus the pending request produced four and crossed the cap. These are arithmetic examples of the inspected code, not additional historical test results.
The shared ledger solved visibility, approximately
The ledger was the part that connected otherwise independent sessions. Each hook invocation wrote into the same file before counting recent records. A session did not need to know which conversation had requested the other work; it only needed to see that other dispatches had recently happened.
Because every session used the same ledger, the guard could include recent dispatches from other sessions in its estimate. That gave it a shared count to check before starting another agent.
        os.makedirs(STATE_DIR, exist_ok=True)
        # atomic append of our timestamp
        with open(INFLIGHT_LOG, "a") as f:
            f.write(f"{now:.3f}\n")
Explain this code line by line
- Line 1: Ensure the shared state directory exists. An existing directory is accepted.
- Line 2: The historical comment describes this as an atomic append; that claim applies to the append step, not the whole ledger update.
- Line 3: Open the common ledger in append mode so this step writes at the end rather than replacing existing records.
- Line 4: Write this attempt’s timestamp, rounded to three decimal places, followed by a newline.
The hook then read the file, parsed valid timestamps and kept entries no older than the configured 120-second window. Old entries were discarded so an abandoned record would not block dispatch forever. That avoided the need for every worker to report completion. The cost was that the ledger could not actually tell when a worker finished.
                    if now - ts <= ttl_sec:
                        kept.append(ts)
Explain this code line by line
- Line 1: Subtract the recorded timestamp from the current time and compare that age with the expiry window.
- Line 2: Keep the timestamp when it passes the age check; each retained record contributes one to the ledger count.
A quick worker could finish while its timestamp still counted. A slow worker could outlive its timestamp. A refused attempt also remained in the ledger because recording happened before the allow/block decision. The live-process check compensated for some long-running work, but only for processes matching its command-line pattern. This was a window of recent dispatch activity, not a lease held until completion.
The update also had a concurrency limit of its own. Appending a record was followed by reading, pruning and rewriting the file without a lock. Those operations did not become a single transaction merely because the first write used append mode. One invocation could rewrite a set that did not include another invocation’s newer append. The retained code does not establish that every race only overcounts safely.
The shared ledger was useful, but it was still an estimate. It could miss a concurrent update or count a finished attempt, so I could not treat it as an exact inventory of running agents.
“Available memory” was a decision input, not a promise
The memory helper called the macOS page-statistics command, read the page size, and converted selected page counts into a number the policy could compare with a floor. It included free, inactive, speculative and purgeable pages. This was deliberately more informative than looking only at a single headline “memory used” figure, but it was still an estimate of reclaimable headroom.
    reclaimable = (
        pages("Pages free")
        + pages("Pages inactive")
        + pages("Pages speculative")
        + pages("Pages purgeable")
    )
    return reclaimable * page_size / 1048576.0, page_size
Explain this code line by line
- Line 1: Begin the total of selected page categories.
- Line 2: Include pages labelled free by the command output.
- Line 3: Include inactive pages as part of the reclaimable-memory estimate.
- Line 4: Include speculative pages.
- Line 5: Include purgeable pages.
- Line 6: Close the arithmetic expression.
- Line 7: Multiply the count by bytes per page, divide by 1,048,576 to express it in MiB, and return both the estimate and page size.
The configuration called its units MB, while this conversion used binary megabytes, or MiB. A floor of 4,096 in the file therefore meant 4 GiB in this helper. That distinction is worth making because a technical explanation should describe what the code computes, not silently reproduce an imprecise variable name.
The implementation report itself acknowledged that the estimate was optimistic, particularly because it counted inactive memory. Being potentially reclaimable does not mean every byte is instantly available without cost. That was why the worker cap remained important. A memory floor alone could approve several requests while the machine still looked comfortable, just before those workers expanded their contexts.
Neither input reserved memory. The check described conditions at dispatch time; it could not guarantee the size of a worker’s future allocations. A later browser spike or a larger-than-expected context could still consume headroom after the request had passed.
Two workers first, then three
The immediate revision is easy to lose in a reconstructed story. The implementation report described a MacBook cap of two. The handover described a final cap of three. Reading both as if they were one unchanged configuration would create a contradiction. The retained commits show the sequence: the initial policy used two, and the next revision changed that field to three. The hook itself stayed the same.
That matters because three was a subsequent choice, not the threshold exercised by the initial third-dispatch blocking test. The handover also called the final cap optimistic. Three context-heavy workers still represented substantial potential demand on a laptop carrying other applications. The code evidence supports the configuration change; it does not supply a new endurance benchmark that proves three is always safe.
| Policy | Initial state | Immediate revision | Meaning |
|---|---|---|---|
| MacBook worker cap | 2 | 3 | Count estimate above the cap blocks dispatch |
| MacBook memory floor | 4,096 MiB | Unchanged | Low estimated headroom blocks dispatch |
| Recent-dispatch window | 120 seconds | Unchanged | Expire old attempts, not confirmed finished workers |
| MacBook decision mode | Block | Unchanged | Refuse the tool call when a reason is present |
| Desktop policy | 10 workers; 8,192 MiB; warn | Unchanged | Warn without refusing; not a universal safe capacity |
| Default policy | 2 workers; 3,072 MiB; block | Unchanged | Fallback for other host classifications |
| Tripwire | Warn 3,072 MiB; critical 1,536 MiB | Unchanged | Notify-only; automatic termination disabled |
The count and memory checks collected the reasons for stopping. With no reason to stop, the hook allowed the request. When a limit was crossed, it wrote a message to the session’s error output before returning the block exit code on the MacBook. The message named the reason, the estimated agent count, the available-memory estimate and the host.
That message was the operator signal I wanted. It explicitly referred to the earlier memory-exhaustion failure and suggested fewer agents, sequential dispatch, closing other sessions or heavy applications, or moving the work to the desktop. A blocked dispatch meant I needed to reconsider the workload before trying to continue. The guard stopped the requested launch; I still decided what work to pause or move.
    if mode == "block":
        _log("blocked", t0, why)
        return 2
    _log("warned", t0, why)
    return 0
Explain this code line by line
- Line 1: Check whether the selected policy requires refusal.
- Line 2: Record a blocked outcome with the reason already constructed.
- Line 3: Return the hook’s block exit code. The historical integration used this to refuse dispatch.
- Line 4: For other modes, record a warning instead.
- Line 5: Return the allow exit code, so a warning does not itself prevent the request.
The guard had a boundary, and the tripwire had another job
This was not a guard around every process launch. The inspected hook recognized Agent and Task calls on its registered Claude path. The handover explicitly warned that external Hermes or agentops gateway work was outside it. A shell job and an unrelated application could consume memory without passing through this checkpoint. A ticket title mentioning multiple clients did not prove that every client had equivalent enforcement.
The implementation also provided an explicit override and several permissive error paths. Malformed input or an unreadable configuration returned allow; a failed process lookup returned zero; a failed memory query could leave the memory floor unchecked. These choices reduced the risk of a broken guard preventing all work, but they also meant “the hook is installed” was not the same as “all risky work is blocked.” The historical source described a fail-open intent. I am not treating that description as an exhaustive proof of every possible error path.
The second layer was a periodic tripwire. The incident report initially recorded it as deferred; the subsequent implementation report and retained script show it being added later in the same day’s remediation. According to the implementation report, launchd ran it every 60 seconds. It sampled memory, notified below the warning or critical thresholds, and throttled notifications to avoid repeatedly interrupting the user.
Automatic termination remained disabled. The script contained an optional termination path, but the configured policy was notify-only. That distinction preserved the operator’s choice about which work to stop. The tripwire could draw attention to memory consumed by applications outside the dispatch hook; it could not undo an oversized admission decision or guarantee a notification arrived before a rapid burst exhausted memory.
What the checks established
The implementation report recorded nine passing checks covering dispatch decisions, the override and tripwire notifications. I have inspected the historical source and configuration for this reconstruction; these are reported checks from that day, not tests rerun on the current machine.
| Historical check | Recorded result | What it established |
|---|---|---|
| Non-subagent Bash call | Allow | The matcher’s no-op path |
| First and second dispatch | Allow | Initial cap permitted those attempts |
| Third dispatch with ledger count three | Block | Initial cap of two was enforced in this test |
| Explicit override with primed ledger | Allow | The configured escape hatch worked |
| Artificially high memory floor | Block | The low-headroom branch produced refusal |
| Warn mode with floor breach | Warn and allow | Mode changed enforcement without removing the warning |
| Normal tripwire sample | Quiet | Healthy samples did not produce warning noise |
| Forced tripwire warning | Log and notification | The warning path was exercised |
| launchd load | Live process, empty error log | The periodic job loaded in that observation |
Those checks were worthwhile. They demonstrated that the central policy could change behavior at the tool boundary. They did not establish the absence of races, complete attribution of every process, the safety of every workload at the revised cap, or freedom from future memory exhaustion. The appropriate result was a tested local guard with known limits.
There was also a smaller baseline cleanup, tracked as VW-815, removing selected background services from the MacBook while preserving the ones still needed. The handover recorded disabling the Hermes gateway and removing the beehiiv MCP entry for the next session, while retaining NetBox. It reported roughly 125 MB reclaimed from the gateway. That was a bounded and reversible reduction in background load; it was much smaller than the multi-gigabyte workers and did not replace admission control.
Recovery meant changing how work entered the machine
The handover left the large digest parked for a solo session rather than treating a successful reboot as permission to repeat the same fan-out. That was the practical change I wanted: work could continue, but the concurrency decision had to acknowledge the machine carrying it. The recovery was not just “close a few tabs.” It combined a leaner baseline, an explicit worker policy, shared visibility and a backstop for memory pressure outside the guarded path.
The practical outcome was a stop-and-explain step before another agent launched. On the guarded MacBook path, a refused request was a warning to me: reduce the fan-out, run the work one agent at a time, or move the heavy job elsewhere. The periodic tripwire provided a separate warning when memory pressure rose outside that path.
Neither part guaranteed that the Mac could never run out of memory again. The guard gave me a way to catch the risky request and respond before adding more load. That was the purpose of the change.
What I took from this
-
Check the machine before adding another worker. A request can be reasonable on its own and still be too much alongside other sessions. I wanted the guard to stop that extra launch before the Mac had to carry it.
-
Make a refusal useful to the operator. The blocked request needed to tell me why it stopped and what I could do next: reduce fan-out, work sequentially, close other heavy sessions or move the job to the desktop.
-
Keep the estimates honest. The ledger and memory reading were decision inputs, not reserved capacity. A passed check did not guarantee that a growing worker would remain safe, and the revised cap was not an endurance result.
-
Keep a separate warning for work outside the guard. The periodic tripwire could flag pressure from other applications. It complemented the registered dispatch check while leaving the decision about what to stop with me.
Next in the journey
With a way to catch oversized agent launches, the journey turned back to what those jobs were bringing into Rootweaver. Next came the outside research lane: getting useful material from a promising video into the platform, and finding where that apparently simple step met practical limits.
Glossary
Technical terms and abbreviations 11 terms
- Subagent
- An agent given a delegated task, with its own working context. Here, several such workers could run at once and add to the Mac’s memory demand. Claude Code: subagents.
- Fan-out
- Used here for splitting work into multiple concurrent agent jobs. Dividing the task does not divide away the shared machine’s resource limit. Related mechanism: subagents.
- Dispatch
- Used here for the request to launch a worker. The guard checks that request before the registered tool call starts the additional work. Related mechanism: hook lifecycle.
- Hook / PreToolUse
- A handler run at a defined point in the agent’s workflow. PreToolUse runs before a tool call; this historical handler checked registered Agent and Task calls. Claude Code: hooks.
- Memory pressure
- How hard the system is working to satisfy memory demand. Apple’s Activity Monitor considers factors including free memory, swap and wired memory; a single free-memory number is not the whole picture. Apple: memory usage.
- Fail-open
- Used here for error paths that allow work to continue when the guard cannot obtain an input. That avoids some false blocks but leaves those requests without the missing check. Related mechanism: hook decisions.
- stderr
- The standard error output stream. The historical guard wrote its refusal or warning here so the session could receive the reason. Python: standard streams.
- Exit code
- The status a process returns when it finishes. Its meaning depends on the caller: in this hook integration, 2 blocked the request and 0 allowed it. Claude Code: exit-code handling.
- launchd
- The macOS service manager. The historical tripwire ran as a scheduled job, separately from the dispatch hook. Apple: launchd jobs.
- Tripwire
- Used here for the periodic low-memory warning script. It samples the machine and notifies the operator; the configured policy did not automatically terminate work. Related mechanism: scheduled jobs.